Blog

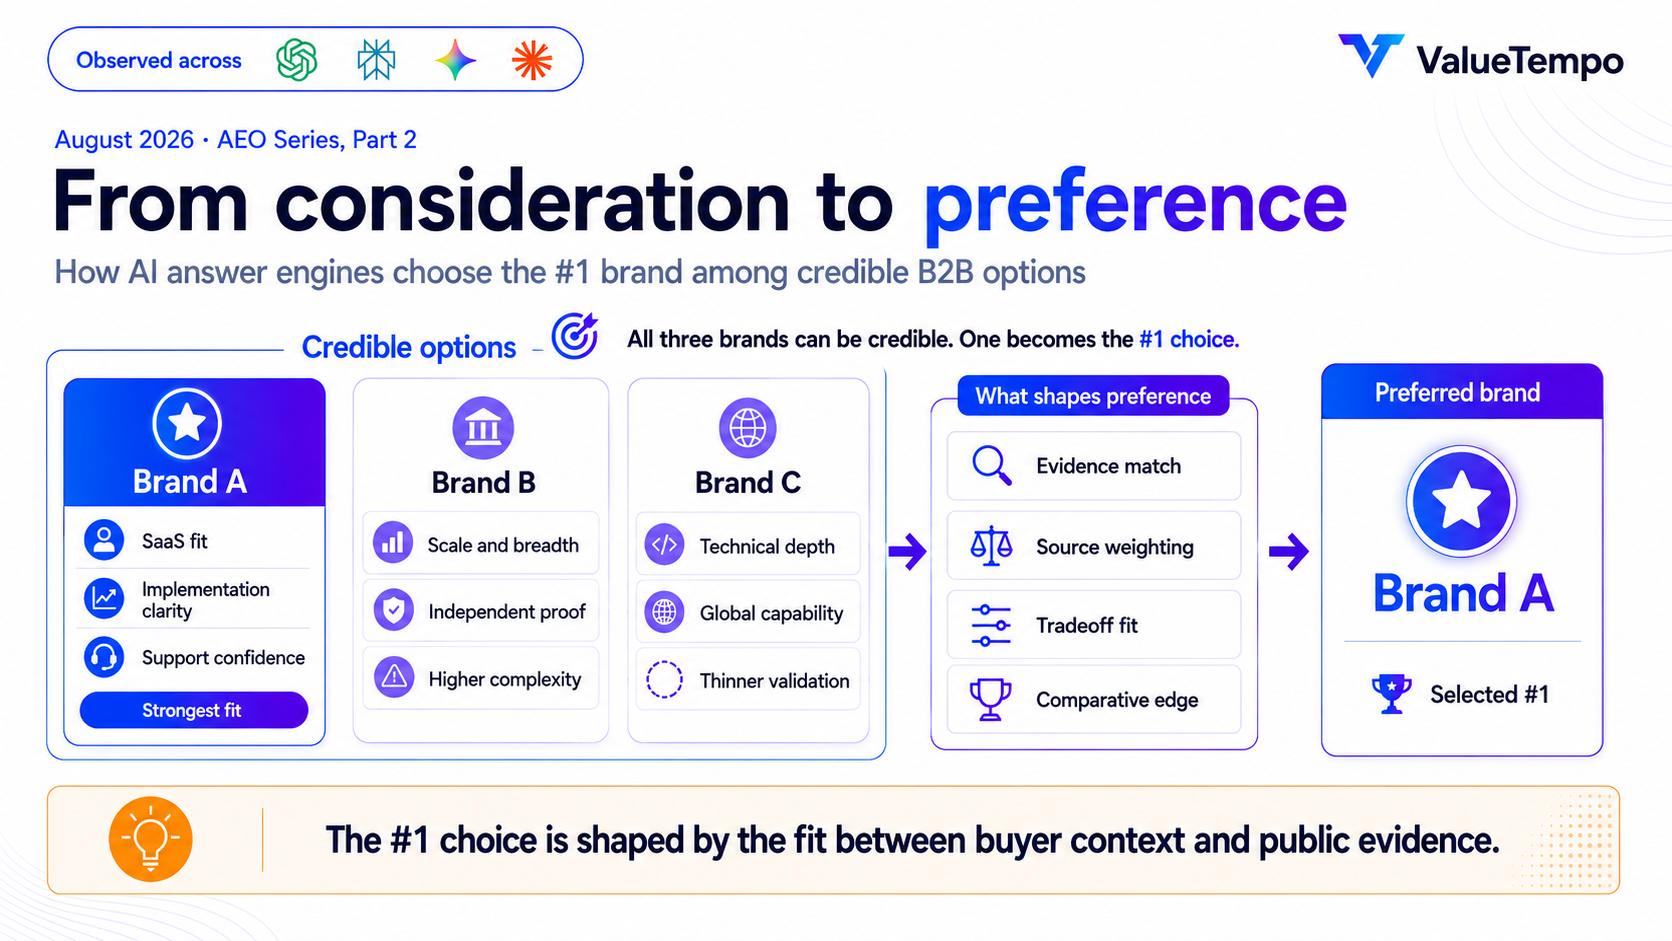
Biggest gap ≠ first fix. Use buyer evidence to find the AEO gaps that actually move decisions, shown as a list of identified AEO gaps with a magnifying glass over those prioritized by buyer evidence.

October 2026

How to Prioritize AEO Fixes Using Buyer Evidence

The biggest AEO visibility gap isn’t always the highest-priority fix. This practical framework shows how to connect AI-search gaps to ICP-fit buyer decisions, choose what to test, and learn from answer-engine and buyer outcomes separately.
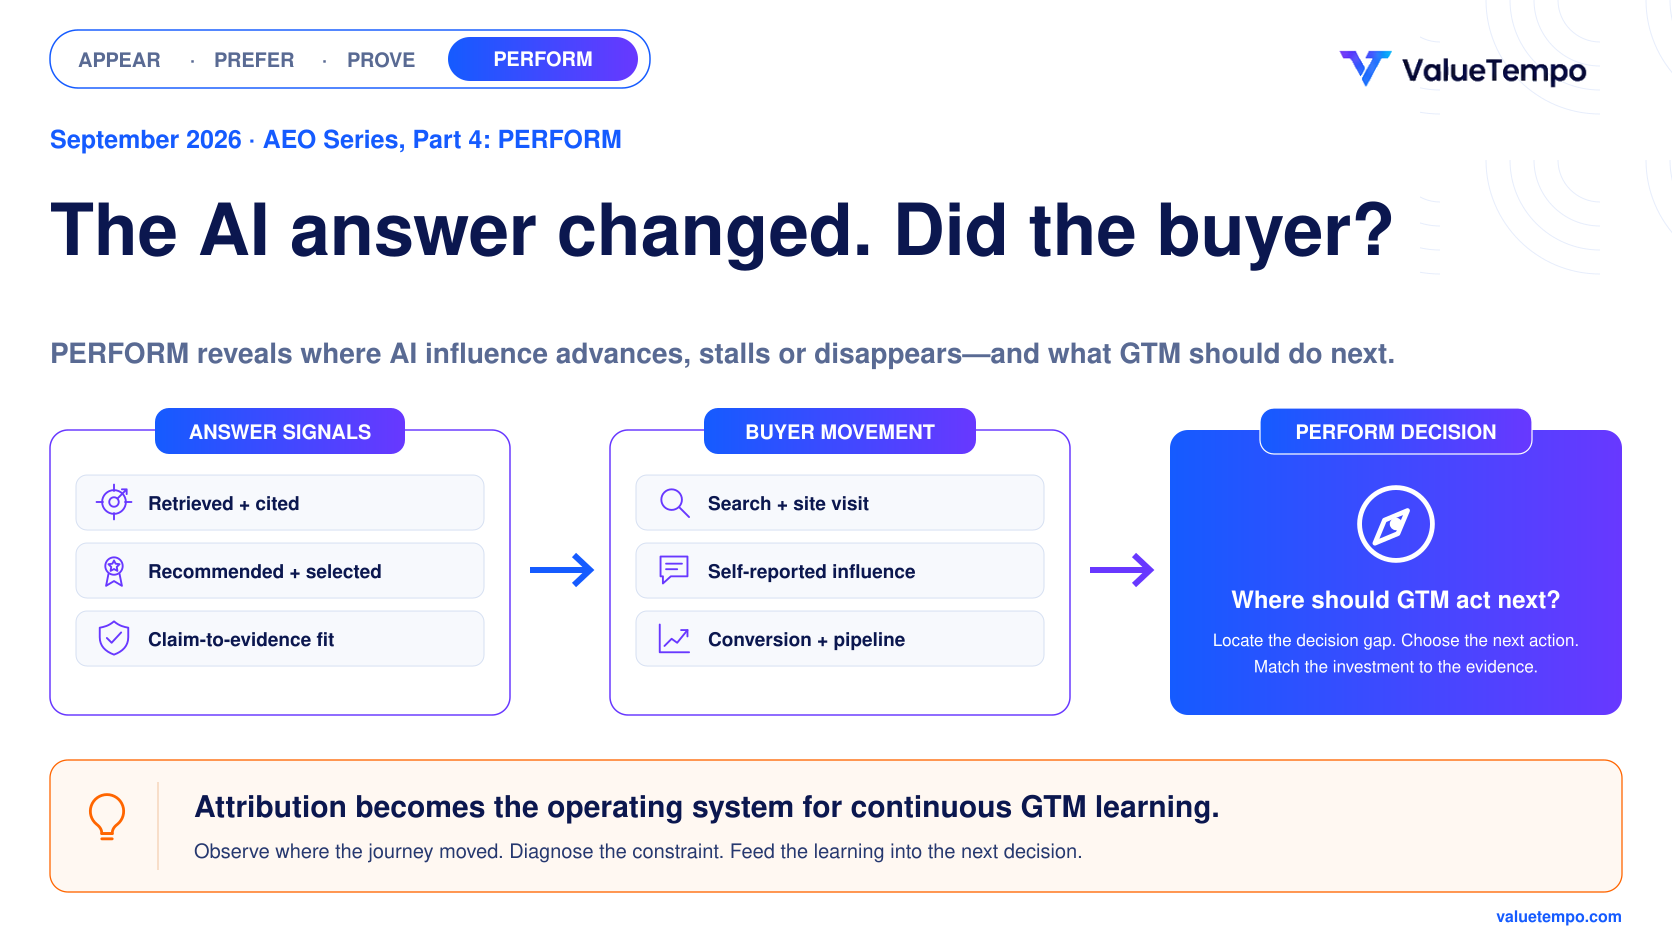
PERFORM connects answer signals and buyer movement to the question of where GTM should act next, matching the investment to the evidence.

September 2026 · AEO Series, Part 4: PERFORM

The AI Answer Changed. Did the Buyer?

AI visibility, recommendation, evidence quality, referral and revenue are not interchangeable metrics. PERFORM connects these signals across the AI-mediated buying journey so GTM teams can locate where influence advances or stalls—and decide what to improve, continue, stop or test next.

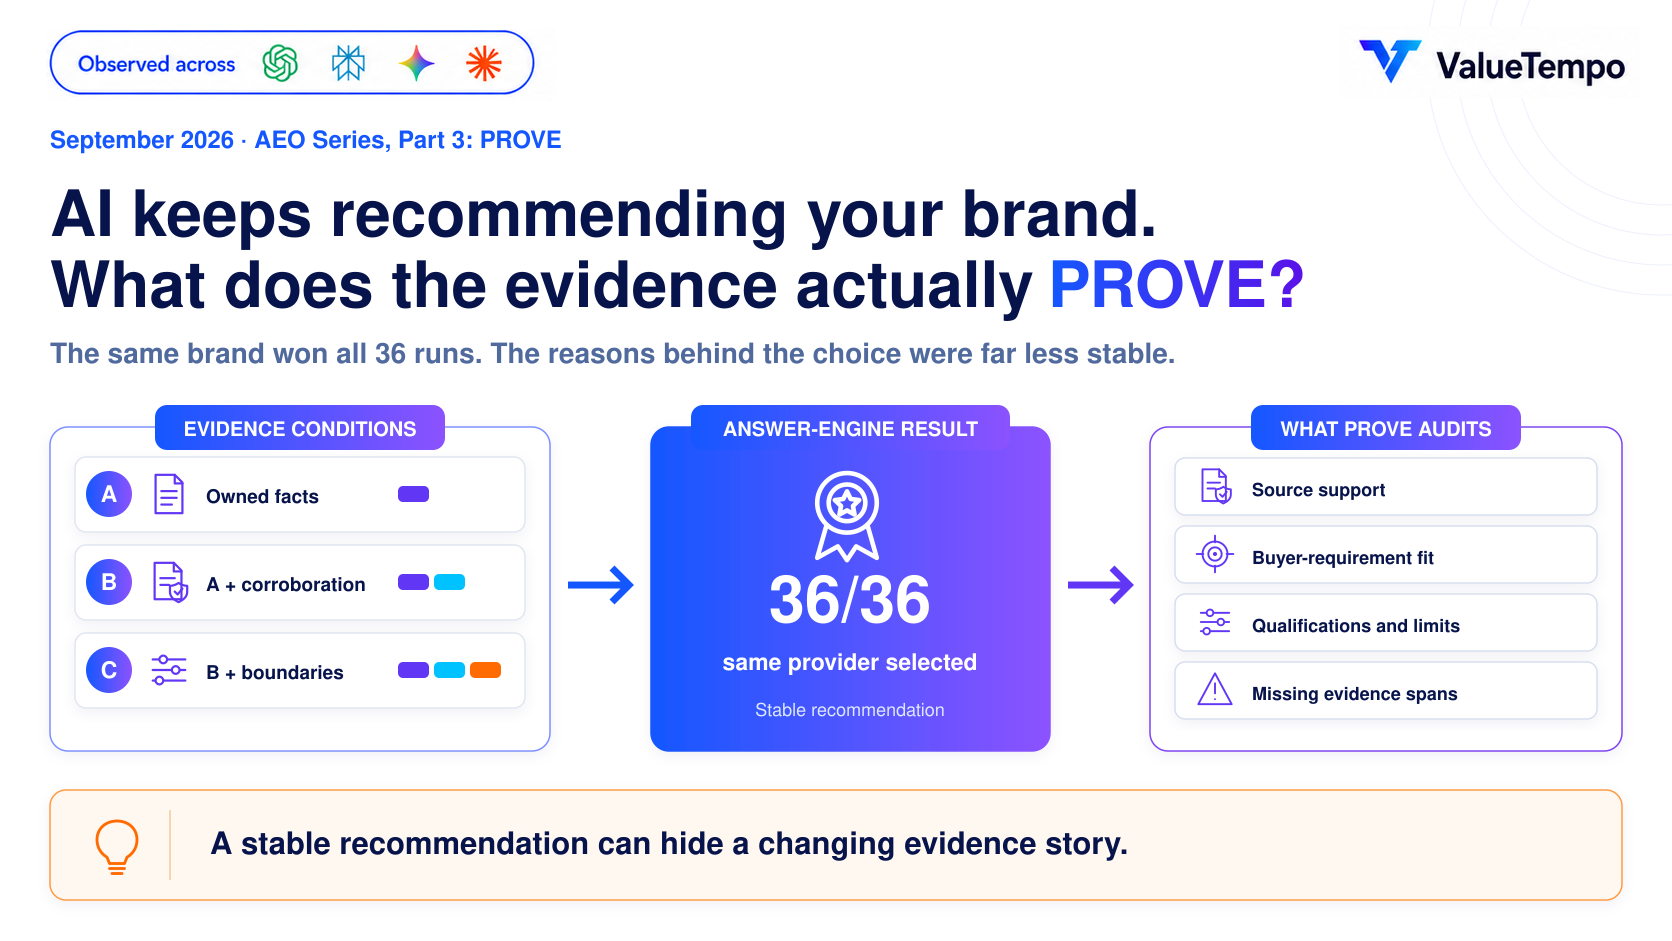
AI keeps recommending your brand. What does the evidence actually PROVE? A 36-run VAT-compliance comparison across three evidence conditions and four answer engines, with the same provider selected in all 36 runs.

September 2026 · AEO Series, Part 3: PROVE

AI Keeps Recommending Your Brand. How Strong Is the Case Behind It?

The same brand won all 36 VAT-compliance comparisons. Yet some answer engines turned credible product facts into buyer-workload conclusions the evidence did not establish. Part 3 introduces PROVE—and shows AEO and GTM teams how to audit the evidence behind an AI recommendation.

The recommendation stayed stable. The evidence story did not.

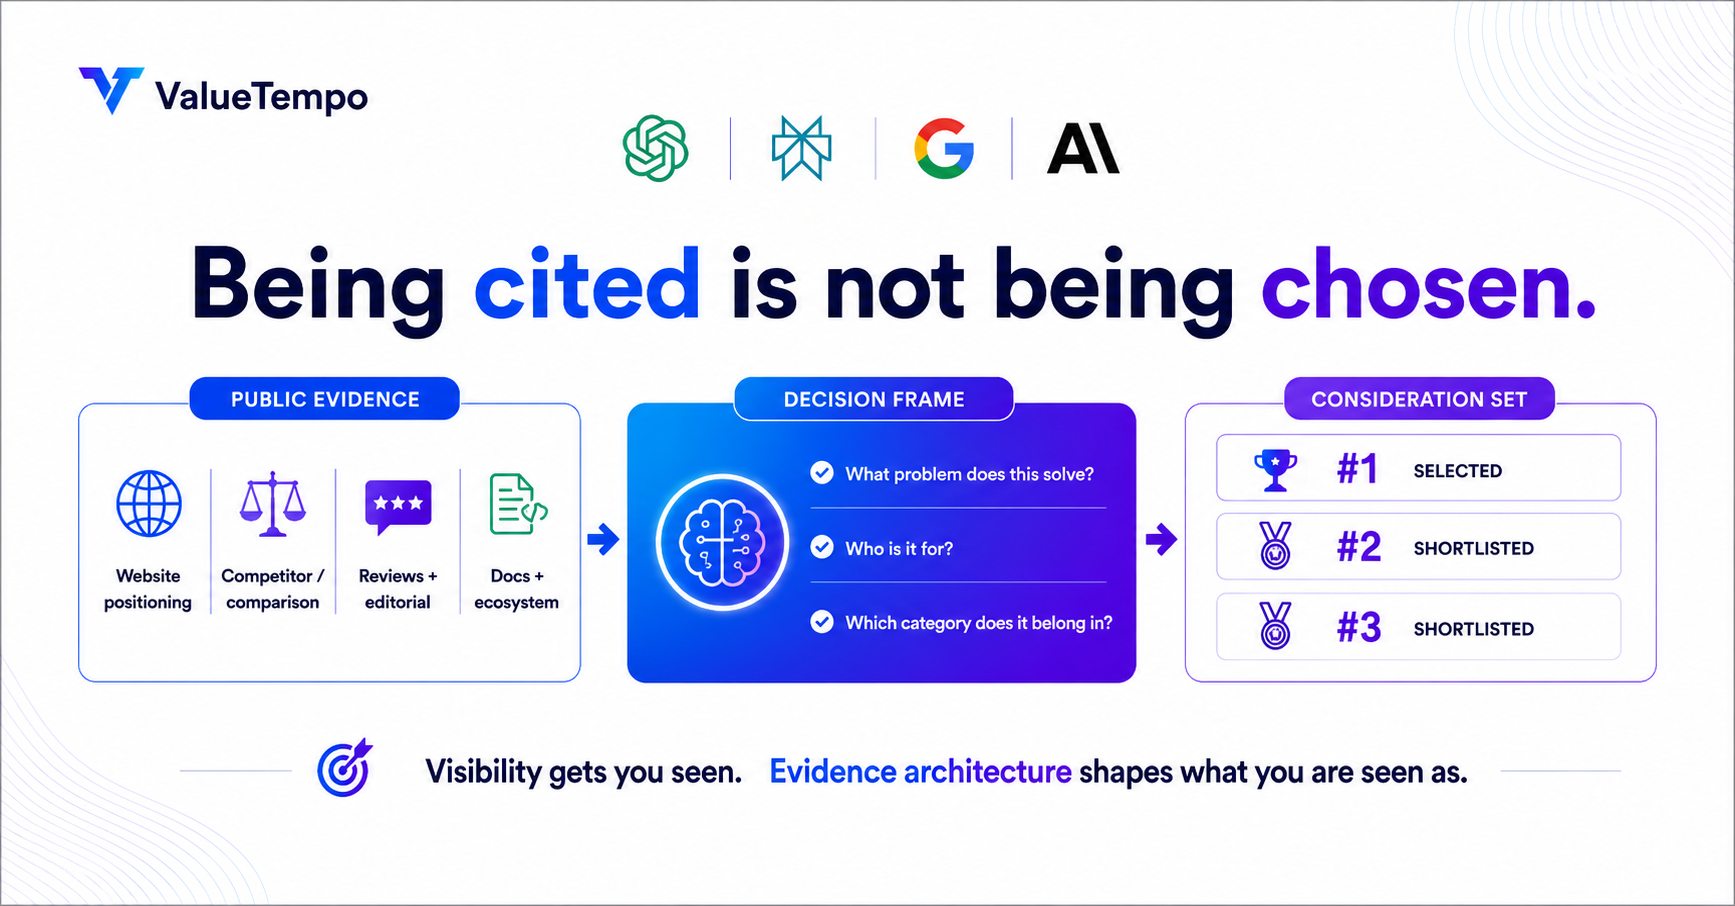
From Consideration to Preference: how AI answer engines choose the #1 brand among credible B2B options. Diagram showing Brand A, B, and C as credible options, what shapes preference (evidence match, source weighting, tradeoff fit, comparative edge), and Brand A selected as the #1 choice.

August 2026 · AEO Series, Part 2: PREFER

From Consideration to Preference: How AI Answer Engines Choose Among Credible B2B Brands

In Part 2 of ValueTempo's AEO series, we examine what happens after credible brands make the shortlist. A repeated VAT-compliance experiment across ChatGPT, Claude, Gemini, and Perplexity shows how buyer context and public evidence shaped which brand became the #1 choice. One credible brand won the #1 spot 10 of 12 times; an equally credible alternative won zero.

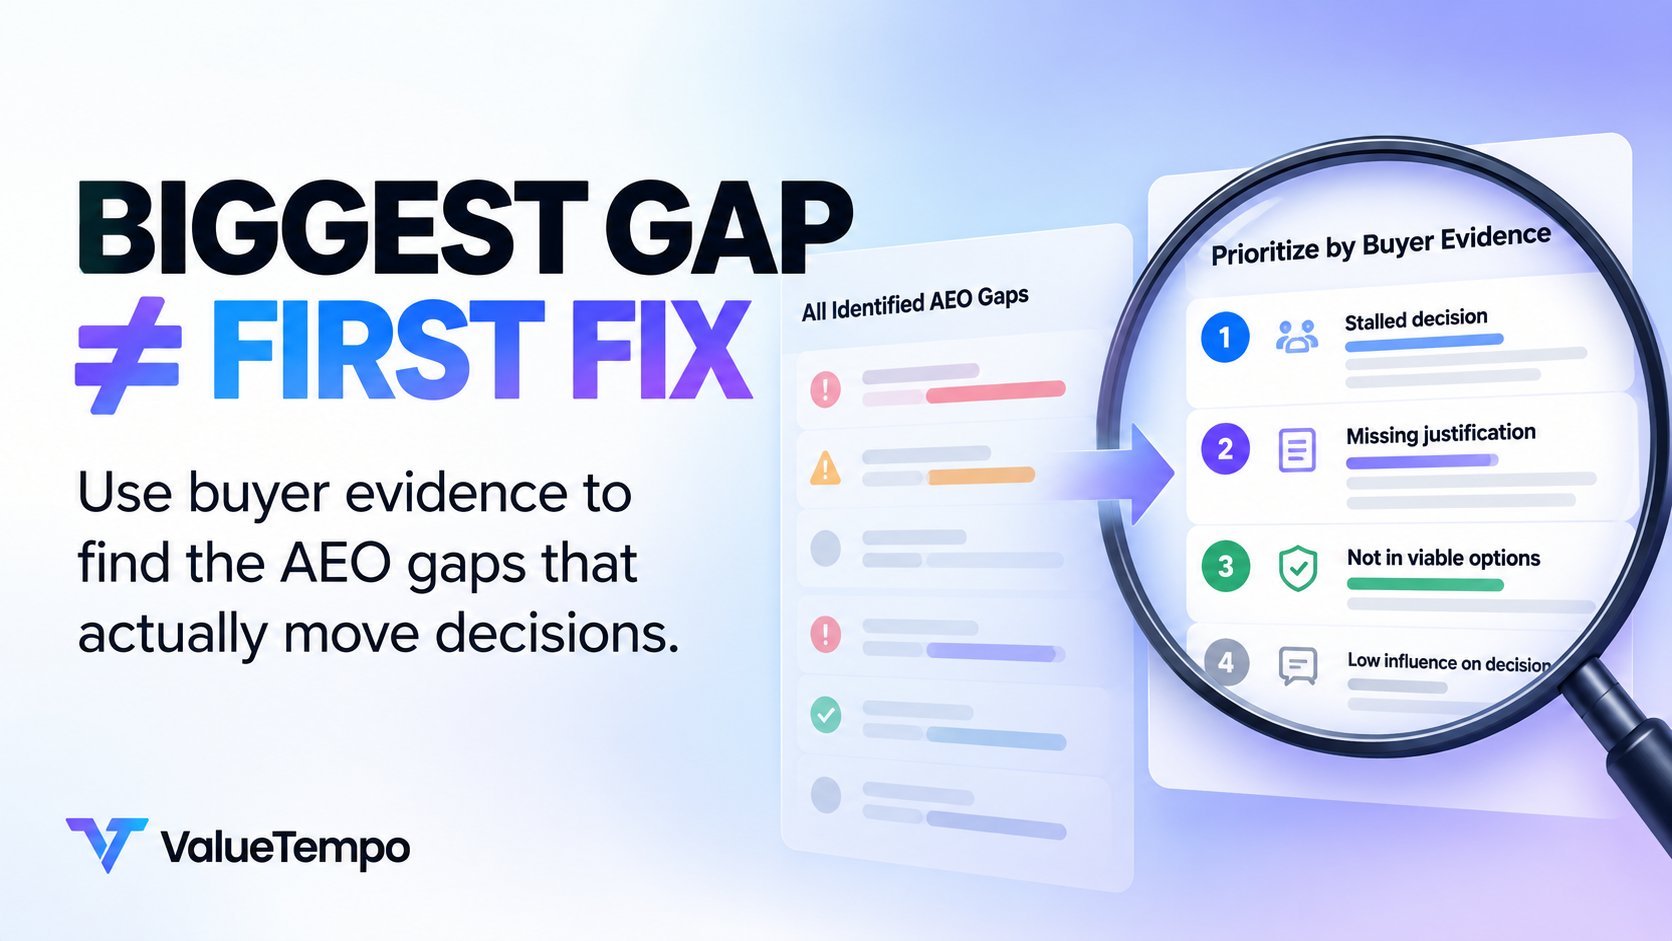
Being cited is not being chosen. APPEAR: how AI answer engines build B2B consideration sets, from public evidence through the decision frame to the consideration set.

August 2026 · AEO Series, Part 1: APPEAR

Being Cited Is Not Being Chosen: How AI Answer Engines Build B2B Consideration Sets

AI recommendations can look stable while the buying logic underneath keeps moving. Across 12 fresh-session runs on four AI answer engines (ChatGPT, Claude, Gemini, and Perplexity), the same brand made the final three 11 times and was selected as the #1 choice in 10. What that reveals about APPEAR, the first AI answer-engine decision state: whether your brand reliably enters the right consideration set for the right buying context.

August 2026 · Benchmark

AI Search Visibility Platforms Are Moving From Measurement to Action. Commercial Evidence Hasn't Caught Up Yet.

AI search visibility platforms are moving beyond measurement into recommendation and action. But across 12 companies, 10 still meter primarily on observation-based units, while recommendation quality remains difficult to evaluate from public evidence. The August benchmark shows where the category is heading, and what GTM teams should watch next.

July 2026 · Benchmark

Why AI Speech Is the Most Buyer-Ready Category We've Benchmarked (And What That Reveals)

We scored 12 AI speech companies on what buyers can independently verify before they engage sales. Every company scored Exemplary — a first in the benchmark. Here's why that happened, and why the gaps that remain are more instructive than the ones that don't.

June 2026

Building GTM Like a Product: Why Buyability Needs a Buyer-Defined Spec

Faster GTM workflows do not automatically create better GTM systems. Why buyability is a GTM system problem, and how a buyer-defined spec closes it.

June 2026

Introducing the May 2026 AI SaaS Buyability Benchmark

We scored 60 AI B2B SaaS companies across 5 categories and 8 evidence dimensions. The market is compressed in the middle, value unit precision is a major separator, and challengers often publish stronger buyer evidence than incumbents. The full benchmark is live — download the report.

May 2026 · Benchmark

The Buyability Gap: A Hidden Cost of Your AI Product Growth

We analyzed 60 AI products across 8 buyer-confidence dimensions. The market is splitting into two camps: gated and buyable. Here is what the data shows.

April 2026

Why a Trust Diagnostic Needs More Than Evals

Three layers of AI-native QA: how the AVS Rubric engineers for evidence integrity, and the verification layer most AI tools skip.

March 2026

A Stable Score Can Still Hide Unstable Evidence

What hardening AVS Rubric across Beautiful.ai, Hex.tech, and ZoomInfo taught me about evidence integrity, trust infrastructure, and building an AI-native diagnostic founders can trust.

March 2026

Why AI Pricing Requires Three Layers: Architecture, Observability, and Trust

A Clay case study - AI pricing works when buyers can predict value, usage, and cost before committing. This article analyzes Clay's new pricing architecture using the AVS Trust Rubric and shows why Clay's pricing architecture improved, but AVS Trust score dropped from 81% to 75%.

March 2026

What I Learned Vibecoding an AI Startup Tool using Lovable + Claude Code

A build-in-public note on what broke, what worked, and what vibecoding an AI product taught me about reliability, production readiness, and trust infrastructure.

February 2026

Trust is the new growth constraint in AI

A practical way to make value, usage, and cost feel predictable — why pricing drift becomes trust drift, and how AVS gives operators a shared map.